aliasing of mutable objects
在一个 list 里,我们 append 一个 object
list=[]
i={1,2}
list.append(i)
之后 query 它,还是 原先的 i
list[0]
但如果我们在 list 里更改它
list[0]|={5}
原先的 i 也会改变
i # return {1,2,5}
解决办法是
list.append(set(i))
这样相当于 append 了一个 copy
httpx.get(url)
httpx是一种modern的用法,比requests多很多功能
import httpx
page_text = httpx.get(url).text
[lambda x: x]
series.value_counts()>=10)[lambda s: s]
或者
s = pd.Series([1, 2, 3, 4])
s.loc[lambda x: x > 2]
""
"hi"
","
"there" # 相当于 "hi,there"
每个"..."之间不需要加逗号。
zip
如果已有同一个名字的.zip,再zip的时候会在.zip文件里添加文件。
所以如果想要overwrite原先.zip文件,需要先删除已有的.zip,
rm -f xx.zip
str.format
用一个空的{},后面.format(x)可以把x添加到{}里
tmpl = "./profile/{}"
tmpl.format("a") # './profile/a'
也可以多个
tmpl = "./profile/{}/{}"
tmpl.format("user", "settings") # → './profile/user/settings'
或者有名称
tmpl = "./profile/{name}"
tmpl.format(name="alice") # → './profile/alice'
X or Value
def send_df(df, *args, href, button=None):
    json_data = df.to_json(orient='records')
    return Form(
        Hidden(value=json_data, name='dataframe'),
        *args,
        button or download_button(' Data'),
        method='post',
        action=href,
        style='display:inline;'
    )
用 or来表示,if button is None/False/empty, use default, else use button
- Using mutable or expensive defaults (lists, dicts, custom objects) as function defaults → dangerous. They get shared across calls. 也就是说,如果arg里是list,可能被改写。所以尽量不要让arg出现mutable default
- Using None + constructing inside → safe and predictable.
match case
之前
def as_pattern(p):
    if isinstance(p,int):
        print(f"You said a {p}")
    elif isinstance(p,str):
        print(f"You said a string {p}")
之后
def as_pattern(p):
    match p:
        case int() as num:
            print('number',num)
        case str() as string:
            print('string',string)
case后可以跟value,string, 也可以跟class,这里的int()和str()就是 class。后面加的as是为了capture matched value。
另一个class的例子
class Point:
    __match_args__ = ('x', 'y')
    def __init__(self, x, y):
        self.x = x
        self.y = y

match points:
    case []:
        print("No points")
    case [Point(0, 0)]:
        print("The origin")
    case [Point(x, y)]:
        print(f"Single point {x}, {y}")
    case [Point(0, y1), Point(0, y2)]:
        print(f"Two on the Y axis at {y1}, {y2}")
    case _:
        print("Something else")
if 后面不一定跟else
x = 5
if x > 3:
    print("x is greater than 3")
plt title里show 逗号
plt.title(f'{len(x_values):,} pairs', fontsize=fontsize)
{variable:,}的格式
也可以定义小数点后几位
{variable:.4f} # 后四位
sampling
可以有不同的概率
import numpy as np

values = np.arange(100)
probabilities = np.random.rand(100)
probabilities /= probabilities.sum()  # normalize to sum to 1

sampled = np.random.choice(values, size=10, replace=False, p=probabilities)
replace=False 意味着取出一个数之后不会再放回去重新pool。
pairwise
instead of using
list(zip(a[:-1],a[1:]))
可以用
pairwise(a)
比如
from itertools import pairwise
numbers = [1, 2, 3, 4, 5]
for pair in pairwise(numbers):
    print(pair)
# return (1, 2)(2, 3)(3, 4)(4, 5)
is vs. ==
- is False: 只包含False
- == False: 其它类似0 或者None也算
defaultdict
在普通的dict[key]里,如果dict没有这个key,会raise error。
但如果a = defaultdict(list),a['key'] 则会返回一个空的list
defaultdict(set) 如果key没有会返回一个空的set
a = defaultdict(set)
a['a'].add('b')
a # defaultdict(set, {'a': {'b'}})
yield vs. yield from
yield 会return 一个 chunk
yield from 会iterate chunk里面的每个item,一个一个的return
def encode(text):
    return [1, 2, 3]

def encode_iterable(iterable):
    for chunk in iterable:
        yield from encode(chunk)

for x in encode_iterable('sss'):
    print(x)

# 返回
1
2
3
1
2
3
1
2
3
如果是用yield,返回
[1, 2, 3]
[1, 2, 3]
[1, 2, 3]
另一个例子:
for chunk in iterable:
    yield from self.encode(chunk)
和下面这个是相同的
for chunk in iterable:
    for token_id in self.encode(chunk):
        yield token_id
安装/update miniconda
wget https://repo.anaconda.com/miniconda/Miniconda3-latest-Linux-x86_64.sh
bash Miniconda3-latest-Linux-x86_64.sh
关上或者重新打开terminal,或者
export PATH="/home/sky1ove/miniconda3/bin:$PATH"
source ~/.bashrc
#or
source ~/.zshrc
防止每次ubuntu启动会自动开启conda
conda config --set auto_activate_base false
第一次启动conda
conda init
init会把miniconda相关的路径加到path里,这样以后就可以conda activate了
conda activate
conda deactivate
用linux
不知道为什么ubuntu/linux里,比在windows terminal快得多
async & await
用于asynchronous function。比如await bytes.read()
但如果是synchronous function,比如pd.read_csv() 或者pd.to_csv(),这种是order很重要的,不可以加任何await。
如果给await XXfunc 加一个func wrapper,def前需要加上async, 然后用的时候,func前要加上await,否则会报错。
如何区分sync和async呢?
import inspect
inspect.iscoroutinefunction(x.read)
macOS terminal env
python3 -m venv myenv
source myenv/bin/activate
gdown
可以把超过100Mb的文件放到google drive上share link,然后在link里找到ID
把link修改成以下格式
https://drive.google.com/uc?id={ID}
pip install gdown
url = "https://drive.google.com/uc?id=1l_5RK28JRL19wpT22B-DY9We3TVXnnQQ"
output = "fcn8s_from_caffe.npz"
gdown.download(url, output)
# 或者用cached_download,这样如果detect文件,下次就不会重新下载
gdown.cached_download(url, output, quiet=True)
get max cpus/gpus
import fastcore.all as fc
fc.defaults.cpus
parallel
超级好用的,不用额外下载,只需要tqdm,还有progress bar
pip install tqdm
from tqdm.contrib.concurrent import process_map
# or thread_map if io

results = process_map(func, list, max_workers=4,chunksize=256)
chunksize的default是1,如果很多line,会影响速度。
max_workers是min(32, os.cpu_count() + 4),会在cpu的数量基础上加4,保证速度更快。
好用的
pip install tqdm_joblib

from joblib import Parallel, delayed
from tqdm import tqdm
from tqdm_joblib import tqdm_joblib

# Enable tqdm within joblib
with tqdm_joblib(tqdm(desc="Processing Files", total=len(item_list))) as progress_bar:
    dfs = Parallel(n_jobs=-1)(delayed(func)(item) for item in item_list)
parallel fastcore (不好用)
pip install fastprogress
from fastcore.utils import *
import fastcore.all as fc

parallel(func, items, n_workers=fc.defaults.cpus,progress=True)
#注意如果用progress=True需要提前安装fastprogress
parallel pandas
pip install pandarallel
pandarallel.initialize(nb_workers=32,
                       progress_bar=True,
                       use_memory_fs=False, # necessary for jupyter notebooks
                      )

out = df.col.parallel_apply(func)
out
另外注意,parallel里需要把output item pickle,class是不能被pickle的,所以如果输出是class object会报错,需要转换成dictionary,如下:
class to dict
如果用到了fastcore里的store_attr(),class object 转成dict时候用 obj.stored_args
如果是正常的class,用__dict__
dict iterate
当iterate dict的时候,for i in dict: ... , i是key,只有key会被iterate,相当于for i in dict.keys()
所以用sorted(dict, key=dict.get) 给入到key的item是key, 然后dict.get func里得到的是key,会返回value,所以会用返回的value排序。返回的是排列好的key的list。
如果想要返回排列好的dict,那么sorted里面用dict.items()
dict.items()返回(key,value)的tuple,
sorted(dict.items(), key=lambda x: x[1], reverse=True)
dict.items()可以iterate,但type是dict_items, 不可以dict.items()[:10], 所以如果想要query,需要先转换成list
list(dict.items())
combine two string
'a' + 'b' # 'ab'
b'\x01' +b'\x01' # 'b'\x01\x01'
zip 可以当做transpose
zip返回iterator,如果我现在有一个list of strings (类似matrix), transpose它们的办法是 zip(*list_strings)。
o=['#####', '.####', '.####', '.####', '.#.#.', '.#...', '.....']
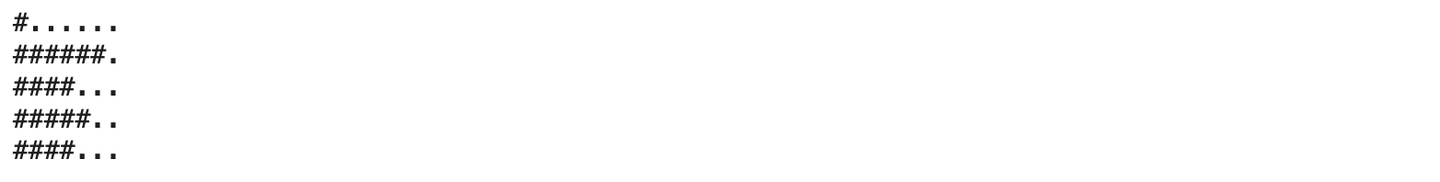
添加图片注释,不超过 140 字(可选)
list(zip(*o))
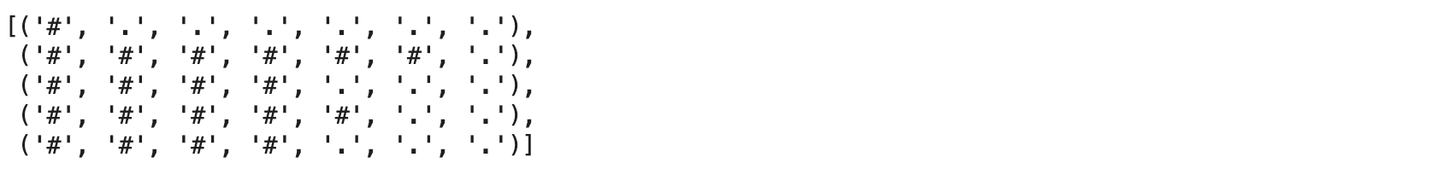
添加图片注释,不超过 140 字(可选)
或者用next查看
next(zip(*o)) # output ('#', '.', '.', '.', '.', '.', '.')
可以把每行join起来
[''.join(i) for i in zip(*o)] # output ['#......', '######.', '####...', '#####..', '####...']
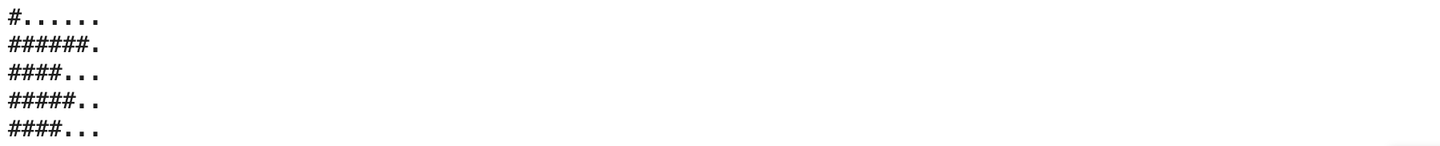
添加图片注释,不超过 140 字(可选)
dict(zip(list1,list2))
可以把两个list join起来变成dictionary
比如我有一个list of paths (Path),想要用stem作为key
dict(zip([p.stem for p in paths], result_list))
global variable
function里可以放global a 就能和 function外的a同步了
设置环境变量
command: export A="aaa"
in python
import os
os.environ['AA']='ssss'
dictionary function
可以用dictionary of functions 替代 if, elif, elif, 比如
func = {'XOR': lambda x,y: x^y, 'OR': lambda x,y: x|y, 'AND': lambda x,y: x&y}
而不用
if a == "AND":
     d = x & y
elif a == "OR":
     d = x | y
elif a == "XOR":
     d = x ^ y
int(string, 2) 转换成二进制
第二位是base number, default 是10
max(list,key=lambda x: ..)
在max里可以用key=func返回最大的item
max(['apple','banana','peach'],key=lambda x: len(x))
mutable 可变的,immutable不可变的
tuple 是immutable,创建之后不可变。tuple可用于作dict的key。速度更快。
list是mutable,创建之后可以append, extend之类的。不可以用作dict key
progress_apply
给df.apply加上progress bar
from tqdm import tqdm
tqdm.pandas()
df.progress_apply()
indices & range
range(number) , number往往指代一个长度,里面的indices是number-1。 比如range(3)是0,1,2。
d[idx]: 比如有个string,d=brwrr,五个字母, 它的每一个indices是从0 到 len(d)-1,可以用[i for i in range(5)], 也就是0,1,2,3,4,来指代。|PS:range(5)不包括5
如果用for i in range(len(d)),刚好可以指代里面的每一个字母。
[d[i] for i in range(len(d))] # output ['b', 'r', 'w', 'r', 'r']
d[:idx], 范围。如果现在我不是指代每一个字母,而是指代一个范围,如果做同样的事情,就会最后少一位。
[d[:i] for i in range(len(d))] # output ['', 'b', 'br', 'brw', 'brwr']
这是因为在:i 里,i是不包含的。所以正确的写法是range(len(d)+1) ,也就是range(6) |PS: 0,1,2,3,4,5
[d[:i] for i in range(len(d)+1)] # output ['', 'b', 'br', 'brw', 'brwr', 'brwrr']
左侧指针: 想象一个指针在每个字母的左侧。0:1 就是在d[0]左侧的指针和d[1]的左侧的指针的范围。
np.vectorize 把string转换成number array
mapping = {'.': 0, '#': 1, 'O': 2, '@': 4}
warehouse_vector = np.vectorize(mapping.get)(warehouse)
warehouse_vector
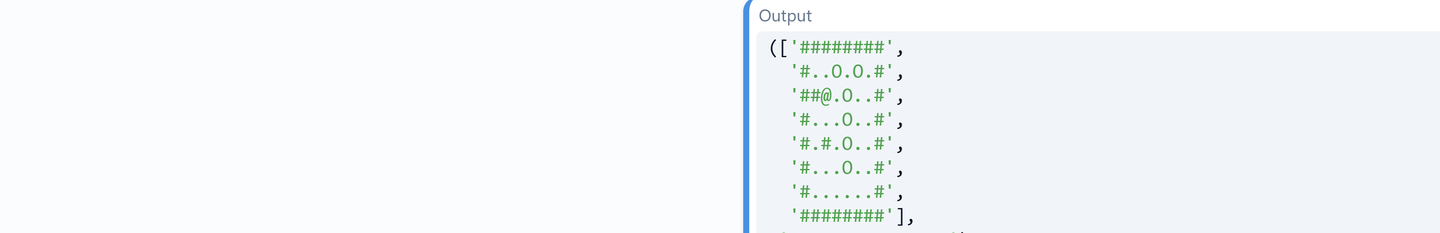
添加图片注释,不超过 140 字(可选)
上面是转换前,下面是转换后
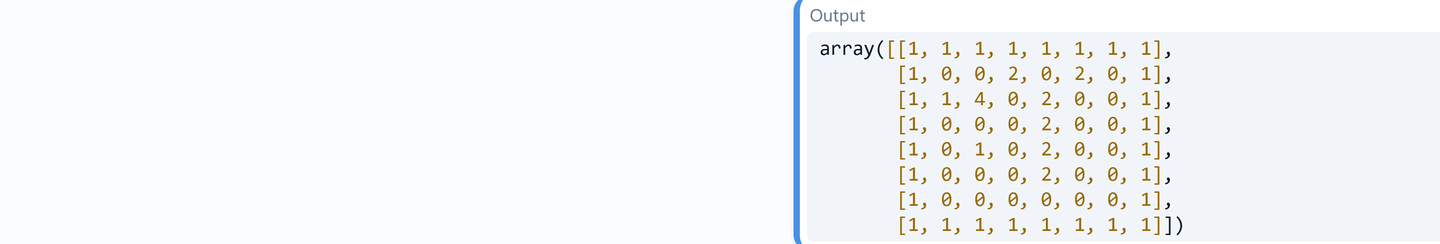
添加图片注释,不超过 140 字(可选)
可以用plt.imshow画图
def plot_grid(grid):
    mapping = {'.': 0, '#': 1, 'O': 2}
    grid_vector = np.vectorize(mapping.get)(grid)
    colors = ['gray', 'darkblue', 'yellow']
    cmap = ListedColormap(colors)
    plt.figure(figsize=(3,3))
    plt.imshow(grid_vector,cmap=cmap,vmin=min(mapping.values()),vmax=max(mapping.values())) # must put vmin & vmax, if any element is absent
    plt.axis('off');
AOC tricks
pipeline:
先用ai把题做出来,知道大概思路,然后用solve it,把每个function分成小function写出来。
过程中用小的example把每一步的结果都显示/画出来,确定是对的,再进行下一步。
list
如果是加单一的item
mylist.append()
加多个item
mylist.extend()
list会保留添加的顺序。
set
把list和tuple转成set的最简单的方法就是set(list/tuple), 而不是 {*list/tuple}
如果是加单一的item,用add; list里用append
s = {1, 2}
s.add(3)     # -> {1, 2, 3}
s.add(2)     # -> {1, 2, 3}(2 已存在)
如果加 iterable items,用update; list里用extend
s = {1, 2}
s.update([2, 3, 4])     # -> {1, 2, 3, 4}
s.update("abc")         # -> {1, 2, 3, 4, 'a', 'b', 'c'}
combine两个set
s = {1, 2}
s |= {3, 4}
print(s)    # -> {1, 2, 3, 4}
set不保留顺序。
时间上,set 和dictionary一样都是1,list是N,会search list里所有的东西。所以用set会更快。
定义一个空的set ,不用{},而是
set()
定义一个不是空的set,直接用{...}
{1, 2, 3, 4, 5}
get overlap item
set(a) & set(b)
merge sets
set(a) | set(b)
merge multiple sets at the same time, 用set().union(*)
set().union(*g['sub_gene'])
set().union({'G1','G2'}, {'G3'}, {'G4','G2'}) # return {'G1', 'G2', 'G3', 'G4'}
如果set里有None,或者NaN,里面也会包含这个,所以需要提前dropna()
df.groupby(col).agg({'x': lambda x: set(x.dropna())})
dict
iterate dict的时候,是iterate它的key
for i in dict: print(i) # 返回的是key
所以可以用
max(dict,key=dict.get)
dict.get里是key,可以根据dict的value进行排序。
merge dict可以用|
dict1 | dict2
查看dict 有没有key不是 if dict[key] 而是 if key in dict, 反向的话不是if not dict[key] 而是if key not in dict
添加单一的item
my_dict = {'name': 'Alice', 'age': 25}

my_dict['city'] = 'New York'
用update添加多个k:v pair,如果key有重复且不同,会更新为最新的value
my_dict = {'name': 'Alice', 'age': 25}

my_dict.update({'city': 'New York', 'age': 30})  # 'age' gets updated
setdefault(key,default_value)
得到dictionary的key的value,如果没被定义,return 第二个position的值作为它的value
adjacency = {}
adjacency.setdefault('b', set())
setdefault(node1,set()).add(node2) 常用于创建adjacency lists
这里会return一个空的set(),可以在空的set里用add增加value
adjacency = {}
adjacency.setdefault('b', set()).add('a')

# output {'b':{'a'}}
pass vs. continue
pass 是一个paceholder,不做任何事情
continue前面满足的话,会skip for loop后面的code
for i in range(5):
    if i == 2:
        continue  # 当i为2的时候,会skip print 2, 所以这个output是0,1,3,4
    print(i)
mutable as argument in func
如果把mutable object作为function的argunent,如果它在function里被mutated,那么下次call这个function的时候会保留上次call的印记。check this: https://florimond.dev/en/posts/2018/08/python-mutable-defaults-are-the-source-of-all-evil
解决办法就是,在pass argument的时候为None,然后function里写, if a is None, a=[] the list. 这样在function里mutate的时候就不会保留之前的mutate痕迹了。
也可以用a??=[]
recursive function
写recursive function的一些trick
for loop recursive function
无需return什么,但需要告诉什么时候结束
下面这一坨,本质上是for loop一直循环,知道graph穷尽
    middle_wires = {*operations[z][0]}
    for middle_wire in middle_wires: # 把这个东西放到function的for loop,后面跟上function本身
        mm_wires ={*operations[middle_wire][0]}  # 把这两行放到function 里
        z_related_wires.update(mm_wires)
        for mm in mm_wires:
            mmm={*operations[mm][0]}
            z_related_wires.update(mmm)
            for mmm in ...
               # till operation[key] not found, # 把这个作为base,放在最开始
for loop recursive function里分为三个部分
- 主体部分,就是for loop 里面关键的两行操作,所以先把这两行放到recursive func里。
- for loop,放到主体部分后面,for loop里放function本身。
- 最后,找到结束语,就是base,如果穷尽,那就return
z_related_wires = set()
def traverse_wire(wire):
    if wire not in operations:
        return
    middle_wires = set(operations[wire][0])
    z_related_wires.update(middle_wires)
    for w in middle_wires:
        traverse_wire(w)
没有for loop, 但是value based recursive function
需要在func里的base和最终return 出一个value。
def traverse_calc(wire):
    if wire in wires:
        return wires[wire]

    op_key = operations[wire][1] # AND, OR, XOR
    a,b = operations[wire][0] # (mjb,nsx)
    a_value,b_value = traverse_calc(a),traverse_calc(b) # (1,0)
    output_wire = func[op_key](a_value,b_value) # (1&0) -> wire

    wires[wire]=output_wire

    return output_wire
上面的这个,base是 if wire in wires: return wires[wire]
function最后面还要加上return output_wire最为最外层的输出,否则会一直loop下去。这个return,决定了traverse_calc(a),traverse_calc(b) 的value
value based recursive function里分为四个部分
- 主体部分计算
    op_key = operations[wire][1] # AND, OR, XOR
    a,b = operations[wire][0] # (mjb,nsx)
    a_value,b_value = traverse_calc(a),traverse_calc(b) # (1,0) # 这里可以先写成wires[a]
    output_wire = func[op_key](a_value,b_value) # (1&0) -> wire

    wires[wire]=output_wire
- return 部分,没有这部分会报错
return output_wire
- base 部分,决定了最里面的值
if wire in wires:
        return wires[wire]
- 最终,自己的function放到哪里
a_value,b_value = traverse_calc(a),traverse_calc(b)
就是function里套function,比如我现在想要for loop 一个nested list,可以一直for loop, 直到item里没有list
def get_sum(x):
  value = 0
  for o in x:
    if isinstance(o,int): value+=o
    elif isinstance(o,list): value+=get_sum(o)
  return value

a = [[1,2],3,[2,[1,1]]]
get_sum(a) # output is 10
if & elif
elif意味着如果if 是false,就用elif,如果有一长串elif,就用第一个True的elif,其余skip
如果全部用if,那么每个if都是independent的,即便True,也会检查下一个if。
下面满足一个,就会省略剩下的elif,即便满足。
x = 15
if x < 10:
    print("x is less than 10")
elif x == 15:
    print("x is 15")  # This runs
elif x > 20:
    print("x is greater than 20")
else:
    print("x is something else")
但如果改成if,会print全部满足condition的x
SimpleNamespace
快速创建class
from types import SimpleNamespace

def ns(a,b,c): return SimpleNamespace(apple=a,banana=b,cat=c)

ns(1,2,3) # output namespace(apple=1, banana=2, cat=3)

k =ns(1,2,3)
k.apple # output 1
json
json.load(f) 和 json.dump(f)
import json

# load through file
with open(file_path,'r') as f: data =json.load(f)

# loads through string text
json.loads(path.read_text())

上面一个是load, 一个是loads,一定要注意!!

# save
with open(file_path,'w') as f: json.dump(data, f)
shutil.copy 可以复制文件
import shutil
shutil.copy(source file path, destination file path)
设置limit
小的数用max设置,大的数用min设置
# 设置一个值的下限(最小值)
value = -10
lower_limit = 0
value = max(value, lower_limit)  # 如果value小于lower_limit,则取lower_limit
print(value)  # 输出: 0

# 设置一个值的上限(最大值)
value = 150
upper_limit = 100
value = min(value, upper_limit)  # 如果value大于upper_limit,则取upper_limit
print(value)  # 输出: 100

# 同时设置上下限
value = 200
lower_limit = 50
upper_limit = 150
value = max(min(value, upper_limit), lower_limit)  # 先限制上限,再限制下限
print(value)  # 输出: 150
reversed(list)
generate 一个相反的iterator
a=[1,2,3]
for i in reversed(a): print(a) # output: 3 2 1
isinstance(value, dtype)
判断当前value的type
o = 1
if isinstance(o,int): return o # output is 1
list.index(value)
在一个list里得到某个value的位置(从0开始)
dnames='zero,one,two,three,four,five,six,seven,eight,nine'.split(',') # make a list

dnames.index('eight') # return 8
list.count(0)
可以count这个list里有多少个0
concatenate string via +
a='8'
b= '6'

a+b # output is '86'
concatenate int
a=8
b=6

a*10+b # output is '86'
%取余
10%3 = 1
两个小圈圈可以想象成除以之后的边角料,也就是余数。
/ 除以
10/3 = 3.333
砍大刀
//除以,得到floor的整数
10//3 = 3

-10 // 3 = -4 (-3.33向小的取,就是-4)
砍两个大刀,把小数点后面的数砍没了。
split
split 的sep default是空格,\t和\n
" Hello world \tthis\nis Python ".split() # output ['Hello', 'world', 'this', 'is', 'Python']
splitline
把\n变成list of items
samp = '''1abc2
pqr3stu8vwx
a1b2c3d4e5f
treb7uchet
'''

lines = samp.splitlines() # output ['1abc2', 'pqr3stu8vwx', 'a1b2c3d4e5f', 'treb7uchet']
.isdigit()
判断是否是数字
'5'.isdigit()
named tuple
create a class
nt = namedtuple('Bodient', ['a','b'])
my_tuple = (10, 20)
print(my_tuple[0])  # Hard to tell what this index means

bodient = nt(a=10, b=20)
print(bodient.a)    # Clear that this is the 'a' field
Dictionary pop
dict.pop(‘key’, None) 可以移除key,同时不反回error,如果第二个位置define了
poetry
install
# install pipx
sudo apt update
sudo apt install python3-venv # requirements for poetry
sudo apt install pipx

# install poetry
pipx install poetry
或者
curl -sSL https://install.python-poetry.org | python3 -
echo 'export PATH="PATH""' >> ~/.bashrc
source ~/.bashrc
如果folder里有poetry 的pyproject.toml文件(里面有tool.poetry之类的),可以用poetry来安装
cd folder
poetry install
class SS(Enum)
原先
class Color:
    def __init__(self, name):
        self.name = name

    def show_name(self):
        return f"The color is {self.name}"

# Create an instance of the class
blue_color = Color("blue")
现在可以写成
from enum import Enum

class Color(Enum):
    blue = "blue"
    red = "red"

    def show_name(self):
        return f"The color is {self.value}"

# Access an enum member and call the method
print(Color.blue.show_name())
通过Enum, Color.blue 就是self.value
getpass可以输入密码
from getpass import getpass

token = getpass("Type your token: ")
会蹦出一个框用来输入密码,储存在token里
调用的时候直接用token即可。
用function来定义param
原先
param = {xxxxx.....}
现在
def param():
    return {xxxxx....}
这样import py file的时候,就不会load很多